TensorNova TensorNova

AI GPU Server Factory & Suppliers in Gitarama

Empowering Next-Generation Deep Learning, LLM Model Inference, and Enterprise AI Architectures Across Southern Rwanda & Beyond

Send Inquiry Now

Industrial AI Integration: High-Performance GPU Infrastructure & Supply Chain Scaling in Gitarama, Rwanda

In the current technological paradigm, artificial intelligence has transitioned from a theoretical research model into the core driver of global industrial and operational transformation. This rapid advancement demands a parallel leap in computational infrastructure. As deep learning networks scale to hundreds of billions of parameters, standard computing clusters are no longer sufficient. High-Performance GPU (Graphics Processing Unit) servers have become the bedrock of modern data centers, research institutions, and enterprise applications. While major hubs in North America, Europe, and Asia continue to absorb massive volumes of high-density compute systems, new hubs of deployment are emerging globally, specifically in high-growth sub-Saharan tech corridors.

Key Industry Trend: The deployment of specialized AI models, such as DeepSeek-R1/V3, LLaMA-3, and advanced visual-language models, requires localized compute clusters that can minimize latency, secure data sovereignty, and operate efficiently within varying environmental conditions.

1. Gitarama's Technological Transition and Regional AI Opportunity

Gitarama, historically serving as the second largest city and a critical geographical and logistical crossroads in the Southern Province of Rwanda, is uniquely positioned to leverage the digital expansion within East Africa. As the Rwandan national government pushes its ambitious Vision 2050 framework, focusing on the transition into a high-income, technology-driven knowledge economy, Gitarama (Muhanga District) has emerged as an primary urban and industrial growth hub. Regional infrastructural developments, including the deployment of national fiber-optic backbones and grid-expansion projects, have set the stage for decentralized server architectures and localized edge-computing nodes.

Rather than relying entirely on centralized server farms in the capital, Kigali, companies, agricultural research agencies, and academic organizations in Gitarama are recognizing the immense advantages of establishing local processing centers. High-density AI GPU servers deployed in Gitarama serve as regional nodes for Southern and Western Rwanda, handling processing workloads for regional agricultural data analysis, geological mapping, financial technologies, and decentralized learning. By operating dedicated local clusters, regional enterprises bypass the high latency, high bandwidth costs, and network constraints associated with transferring raw data overseas or to remote regional nodes.

2. The Global AI GPU Hardware Ecosystem

At a global level, the demand for GPU computing has undergone exponential growth. Standard compute architectures relying solely on traditional Central Processing Units (CPUs) are structurally limited by sequential processing constraints. In contrast, modern AI models require parallel execution of millions of matrix multiplications simultaneously. High-performance GPU servers integrate multiple server-grade GPUs linked via high-speed interconnection fabrics (such as NVIDIA NVLink or AMD Infinity Fabric) to deliver the petaflops of compute performance required for large language model (LLM) training and inference.

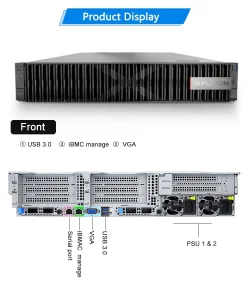
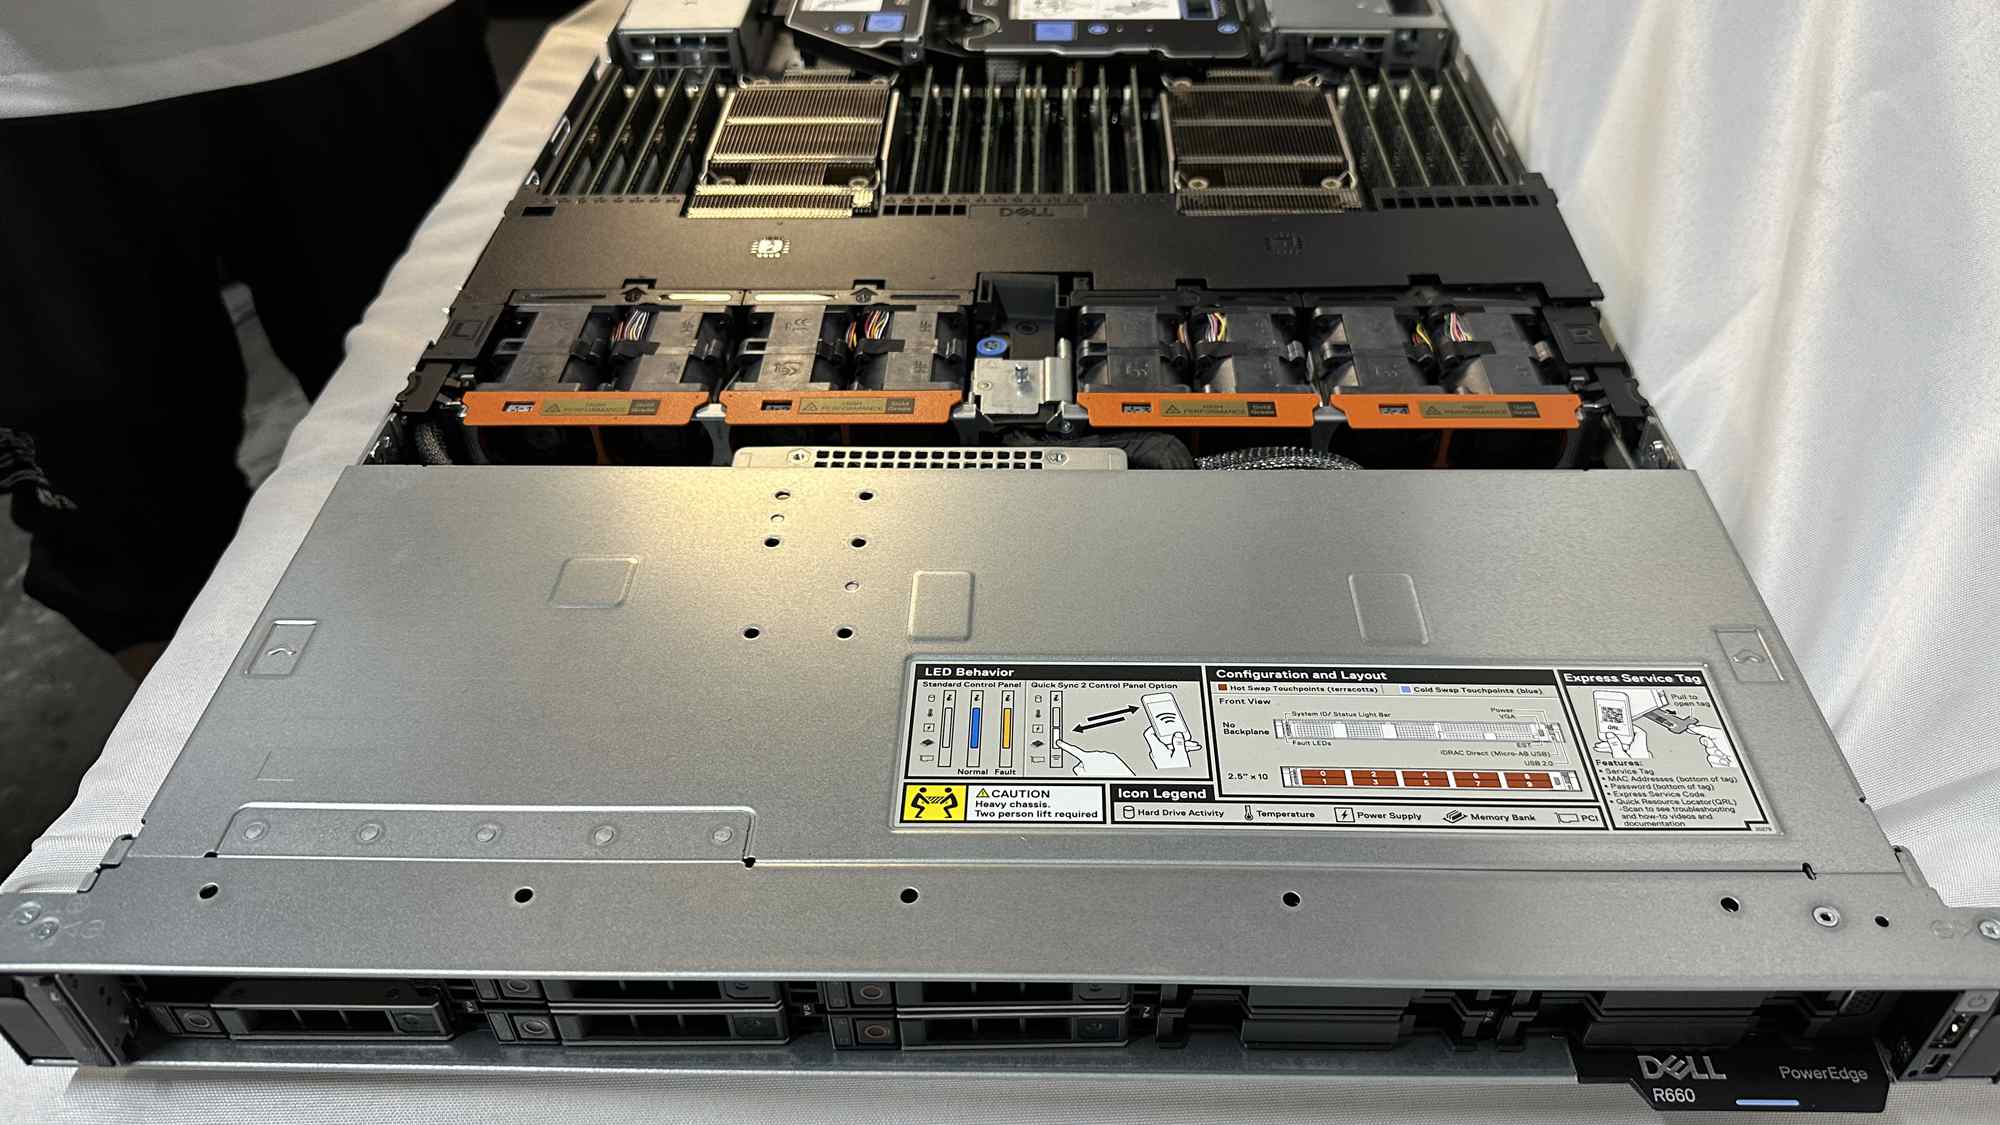
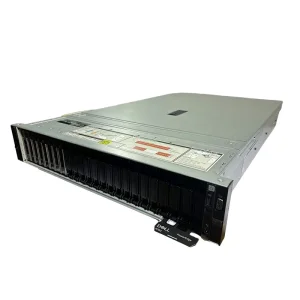
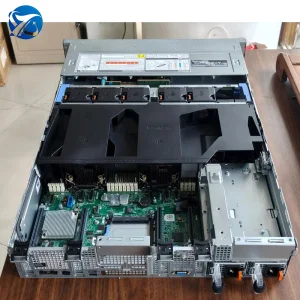
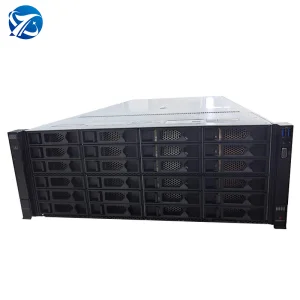
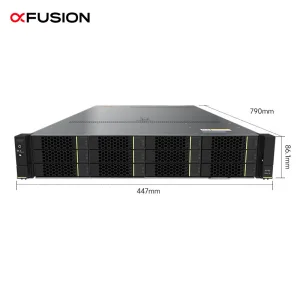
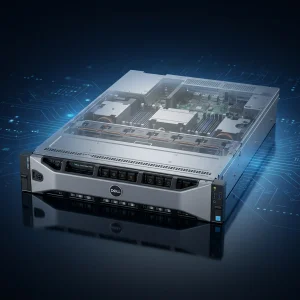
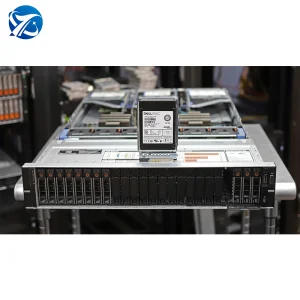
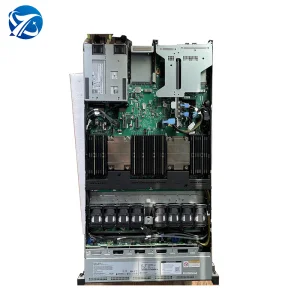
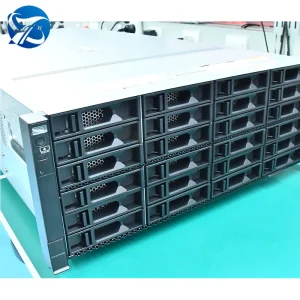
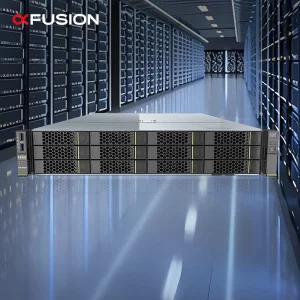
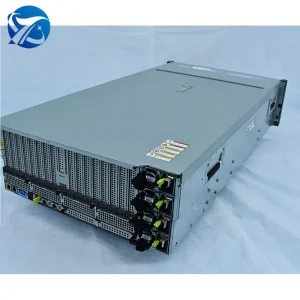
The global enterprise demand focuses intensely on several core server architectures, notably the Dell PowerEdge series and the xFusion FusionServer lines. These platforms provide the necessary dual-socket CPU platforms (supporting the latest Intel Xeon Scalable or AMD EPYC processors), combined with multi-GPU slots (PCIe or SXM form factors) and massive DDR5 memory configurations. These servers are engineered to prevent internal data bottlenecks, pairing lightning-fast processing with NVMe PCIe Gen 5 storage arrays to stream training datasets to the GPU memory without latency delays.
3. Chinese Manufacturing & Supply Chain Synergy: TensorNova

As the primary source of supply for high-performance computing hardware globally, specialized Chinese manufacturing facilities present structural advantages in cost-efficiency, engineering customization, and rapid lead times. Leading this charge is TensorNova, a premium high-performance AI GPU server manufacturer and infrastructure solution provider based in China. TensorNova specializes in custom AI computing development, high-density GPU cluster engineering, and fully scalable enterprise hardware configurations designed for global deployability.

By operating a highly optimized production facility covering 320㎡ and maintaining direct strategic partnerships with over 1,200 global component suppliers, TensorNova mitigates supply chain risks that frequently delay custom server integration. The factory has amassed over 12 years of industry-specific server engineering experience alongside 6 years of specialized international export execution. This comprehensive expertise has allowed TensorNova to achieve an annual export revenue of approximately $8.5 million, shipping high-density systems to key global markets across North America, Europe, Southeast Asia, and the Middle East, with a strong focus on the United States, Germany, Singapore, and the United Arab Emirates.

2016
Company Established
$8.5M
Annual Export Revenue
180+
R&D Engineers
1,200+
Strategic Suppliers

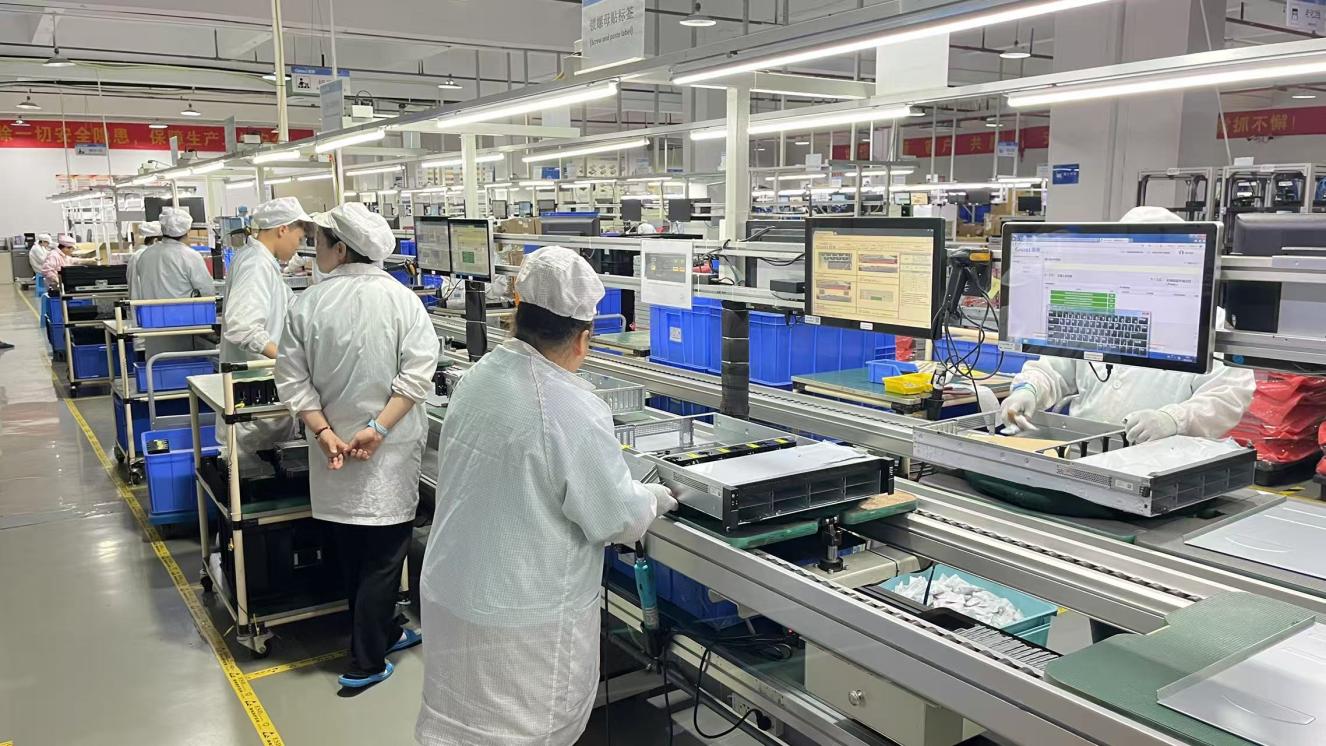
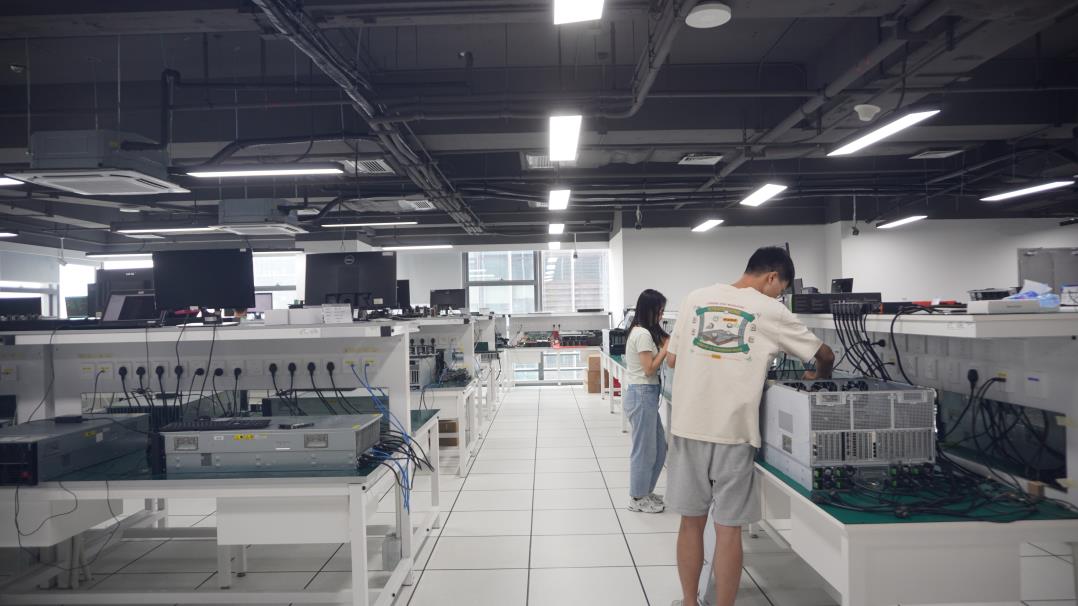
Quality assurance is the core pillar of TensorNova's manufacturing methodology. Every barebone chassis, GPU, storage controller, and network interface card undergoes rigorous ISO9001-based quality control protocols. TensorNova employs 45 specialized quality control inspectors who manage automated hardware stress testing, detailed thermal performance validation, extensive hardware burn-in testing, and realistic AI workload simulation testing (running synthetic training models like LLaMA and DeepSeek-V3). Supported by a strong R&D team of 180 engineers, TensorNova successfully designed and launched over 320 custom products in the past year alone. Their services include comprehensive component customization, chassis layout restructuring, thermal system design (both high-flow air systems and closed-loop liquid cooling), and deep motherboard-level BIOS/BMC optimizations tailored to high-density compute cluster setups.

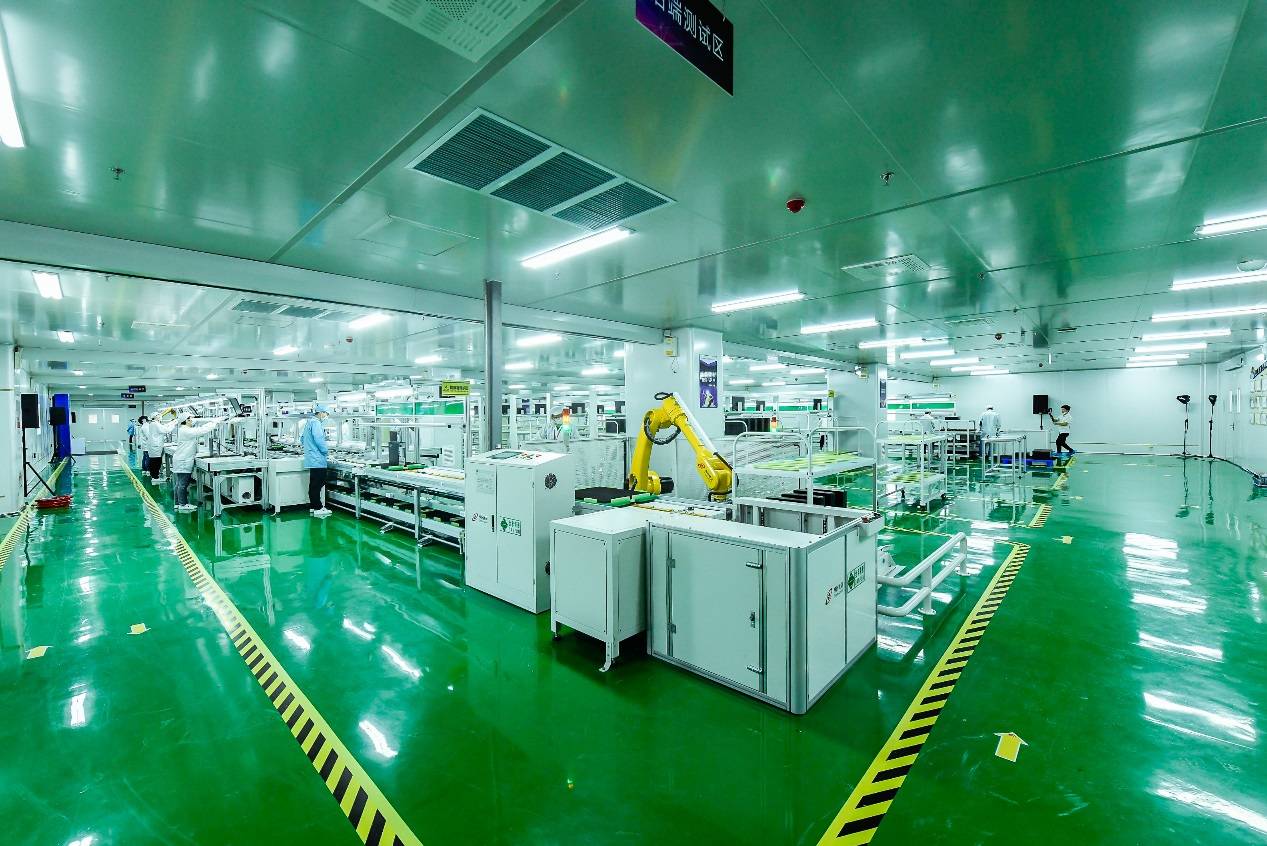
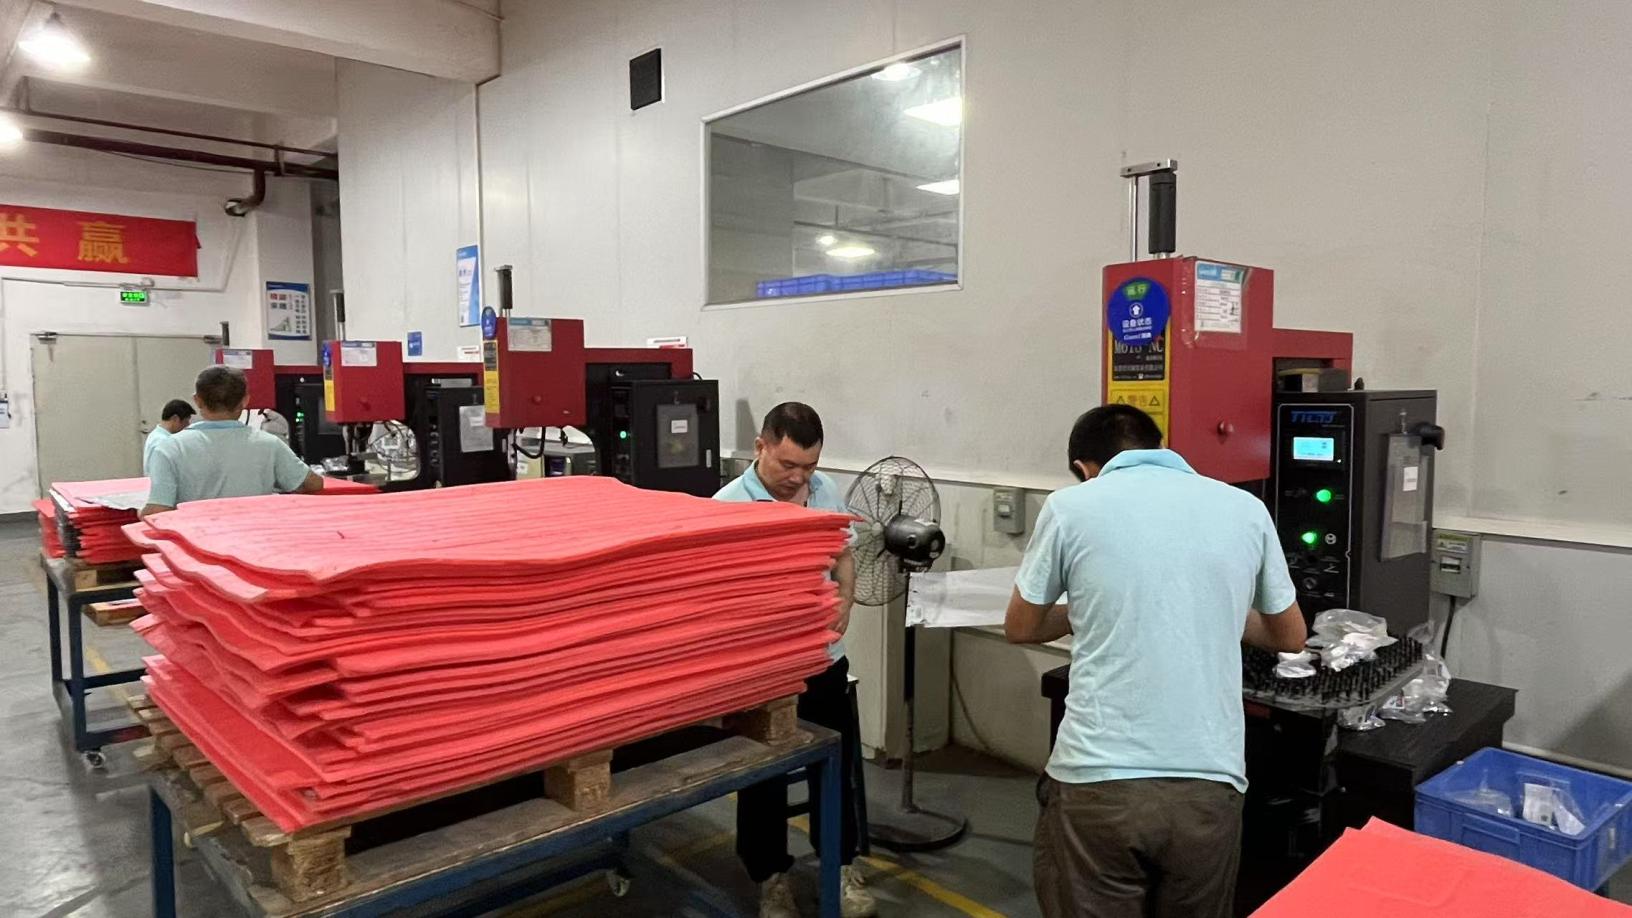
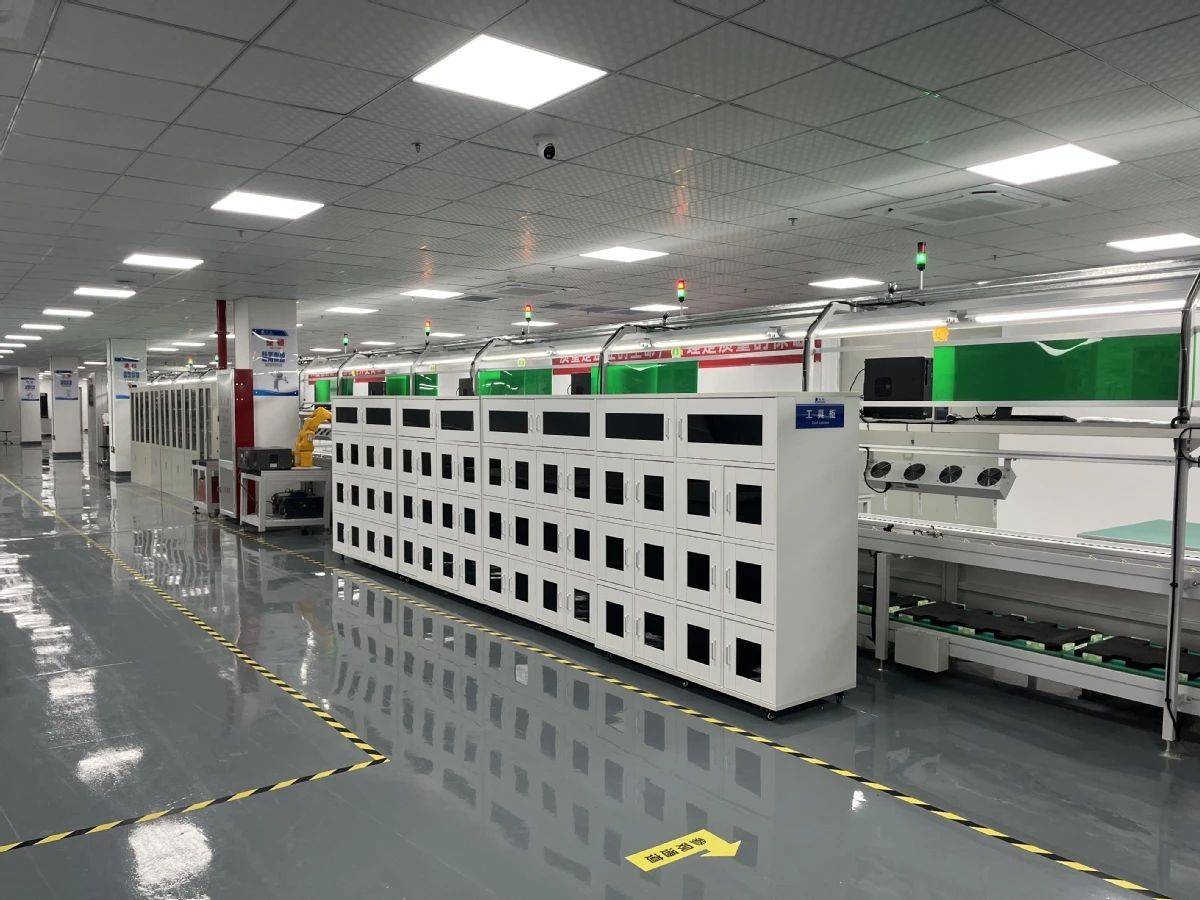
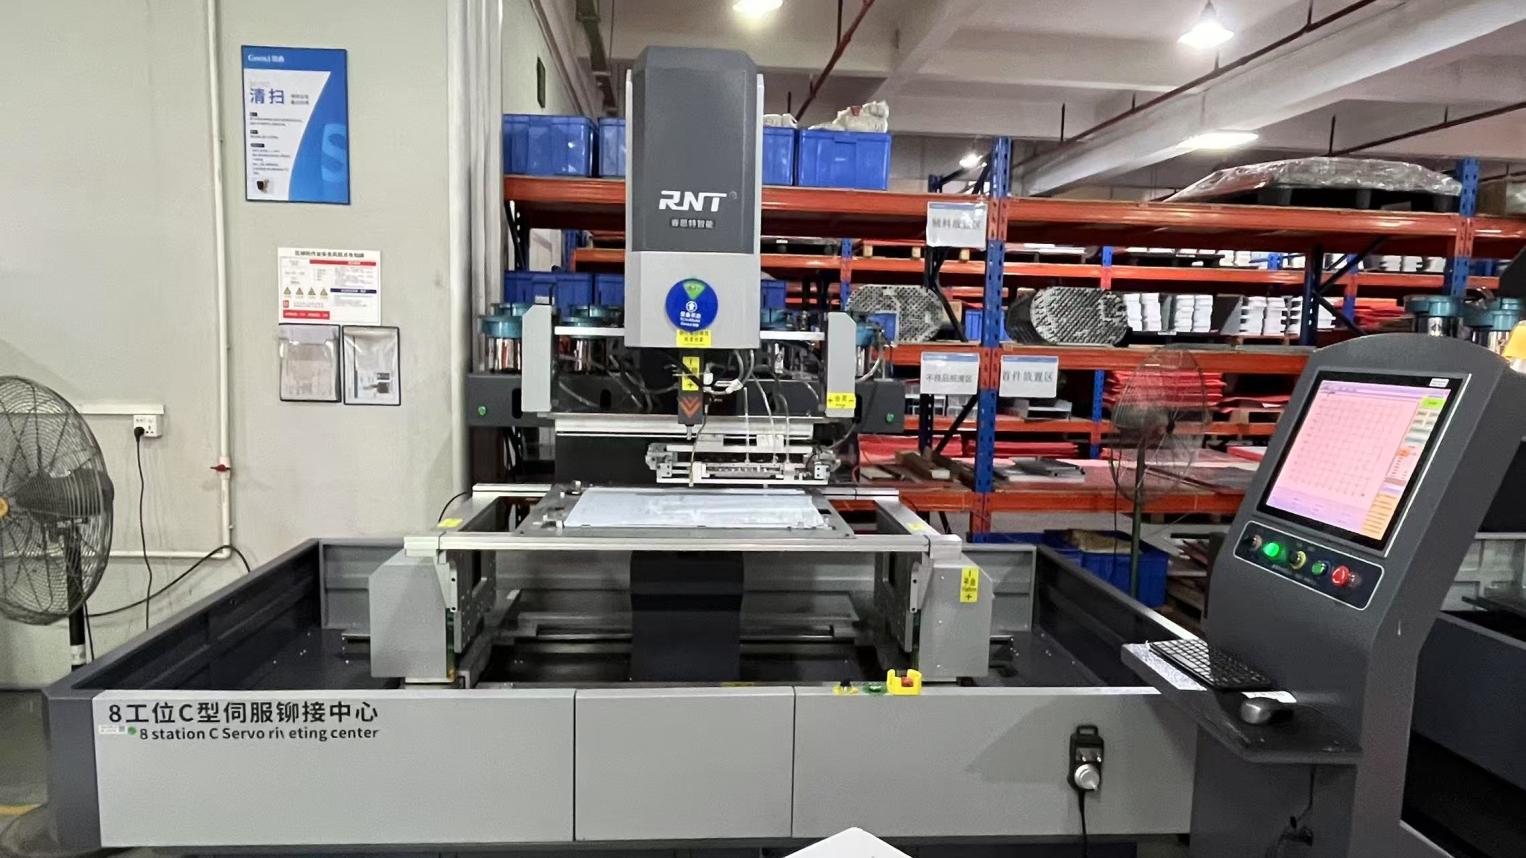
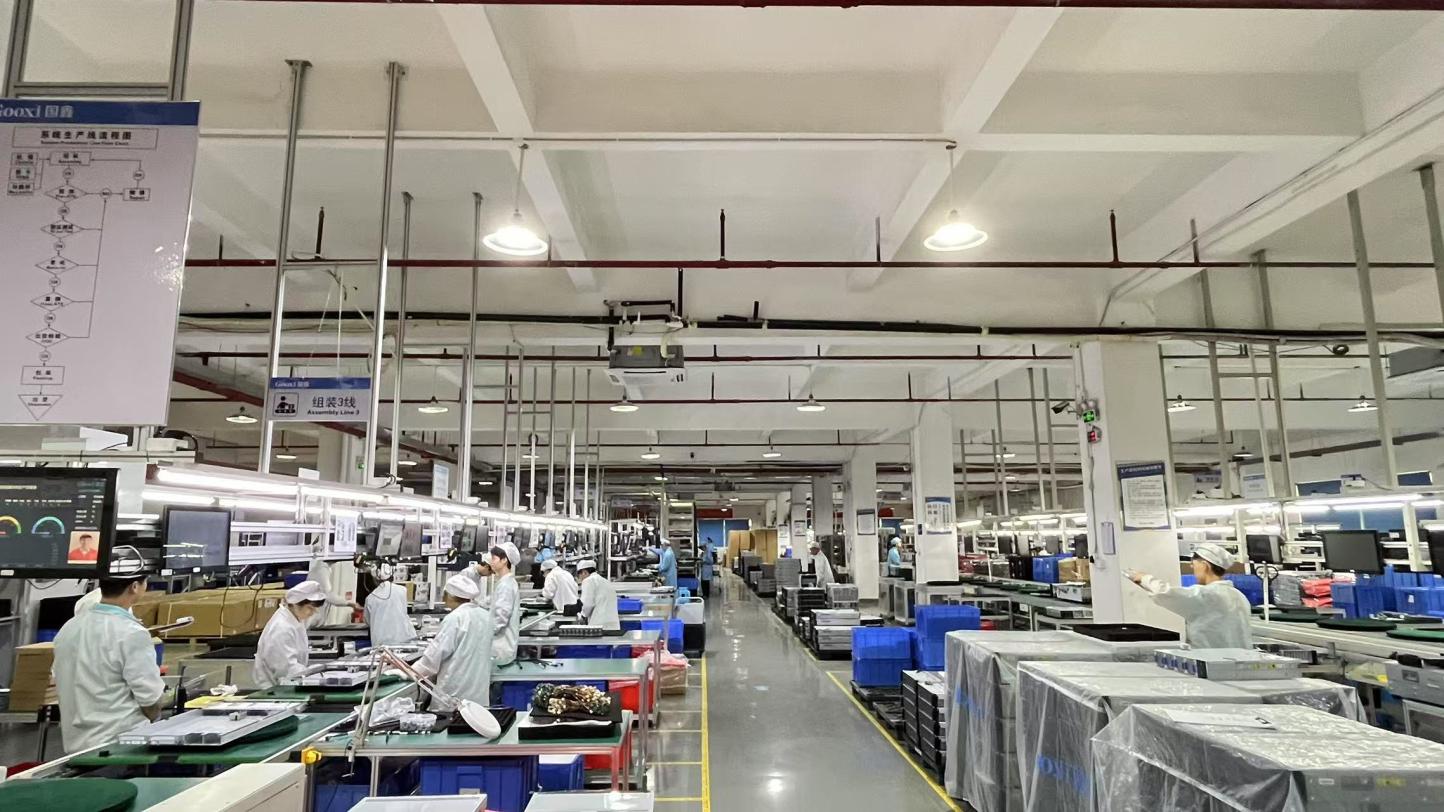
4. Inside the TensorNova Advanced Production & QA Center

Explore our ISO9001-certified integration cleanrooms, custom testing rooms, and GPU cluster burn-in chambers, ensuring extreme hardware stability and low fail rates for global enterprise deployments.

5. Localized AI Application Scenarios in Gitarama and East Africa

The practical value of high-performance compute in Gitarama translates directly into regional development. Key localized applications include:

  • Precision Agriculture and Crop Management: By processing multi-spectral satellite imagery and sensor networks from Muhanga agricultural zones on local GPU arrays, researchers can train models to identify pest outbreaks, soil moisture variations, and yield trends weeks before they affect physical output.
  • Financial Technologies and Micro-lending Risk Profiling: Local credit cooperatives and fintech startups use localized GPU workstations to process large quantities of unstructured transactional and communication data, predicting loan risk dynamics via machine learning without sending confidential records خارج (outside) of regional borders.
  • Language Processing for Regional Communication: Training translation and speech-to-text models on regional dialects like Kinyarwanda and Swahili, requiring hardware designed to process custom acoustic architectures and complex text tokenizations.

High-Performance AI Compute FAQ

Technical answers regarding GPU deployments, network parameters, procurement logistics, and hardware validation.

1. Why should our organization in Gitarama deploy dedicated GPU servers instead of renting cloud resources?
Local physical deployment of AI GPU servers provides significant advantages in terms of ownership TCO (Total Cost of Ownership), network latency, and strict data sovereignty. For tasks such as continuous model training or high-frequency processing of regional datasets, public cloud subscription models quickly incur heavy bandwidth and processing egress costs. In contrast, on-premise Dell PowerEdge or xFusion GPU servers allow companies to run computation continuously without operational pricing variables, securing intellectual property within local networks.
2. How does TensorNova validate server reliability prior to overseas dispatch?
TensorNova runs an exhaustive multi-stage QA protocol overseen by 45 quality control staff. Each system goes through automated hardware stress tests (checking memory parity and PCIe routing integrity), thermal performance validation under synthetic peak states, burn-in validation (minimum 72 hours run-time), and real-world AI workload simulation tests. Systems must operate under extreme thermal conditions with zero packet loss or compute errors before being signed off for global export.
3. Can these servers be customized for training DeepSeek-V3 or DeepSeek-R1 models?
Yes. DeepSeek models require high GPU memory bandwidth and specialized FP8/BF16 compute formats. TensorNova customizes server BIOS, memory allocation, and layout architectures specifically for high-capacity clusters. This includes configuring PCIe Gen 5 switch layouts, custom multi-GPU cards, and liquid cooling setups to manage high thermal dissipation rates without thermal throttling during multi-day training epochs.
4. What are the cooling options for high-density GPU racks in warmer climates like Southern Rwanda?
TensorNova offers dual solutions: high-flow airflow thermal systems with speed-controlled industrial fans, and closed-loop liquid-to-air cooling options. For enterprise data center deployments in Gitarama, liquid cooling systems block heat buildup directly at the processor cores, reducing the required cooling energy of the server room (reducing overall Power Usage Effectiveness - PUE) and keeping internal hardware temperatures within strict operational safety margins.
5. What is the typical lead time for custom server configurations delivered to East Africa?
Due to TensorNova's strong network of over 1,200 suppliers and component partners, physical component assembly and standard validation are finished in 7 to 15 business days. Transport logistics, custom clearances, and final regional transit to locations like Gitarama typically take an additional 15 to 30 days depending on the selected shipping method (ocean freight or express air cargo).
6. Are custom BIOS, BMC, and IPMI management systems available for remote management?
Yes, remote server management is vital for decentralized deployment. All TensorNova GPU servers are configured with industry-standard BMC (Baseboard Management Controller) chips supporting IPMI 2.0, Redfish API, and custom user portals. This enables technical teams located anywhere globally to control physical power cycles, monitor component temperature arrays, update firmwares, and diagnose systems remotely.

Ready to Deploy Enterprise Compute Solutions?

Get in touch with our design engineers for detailed configuration assistance, wholesale pricing tiers, custom thermal architecture simulations, and regional logistics quotes to Gitarama.

Request Technical Configuration & Quote